
LiteLLM's Rust gateway benchmark, checked against LiteLLM's own data
LiteLLM says its Rust gateway has about 7x lower overhead, 9x less memory and 4.5x more requests per dollar than the next-closest gateway. LiteLLM's own benchmark files show a latency and throughput near-tie, a mislabeled widest-pair memory chart, a modeled cost and a config gap, plus Rust leads on CPU and memory.
The LiteLLM Rust benchmark claims roughly 7x lower overhead, 9x less memory and about 4.5x more requests per dollar than the next-closest gateway. Checked against the CSV and JSON files LiteLLM published, the two leading gateways sit within a fraction of a millisecond of each other at most concurrency levels, with throughput gaps under 1%. The 7x figure rests on a 4.54 ms number that appears in no row of LiteLLM’s own sweep.
TL;DR
- In the LiteLLM Rust benchmark’s own latency sweep, the Rust beta and Bifrost v1.6.4 add between 0.33 ms and 0.89 ms of p99 latency at concurrency 1 to 16, and throughput at concurrency 64 is 2,722.2 vs 2,719.1 requests per second.
- The “~7x lower overhead” claim depends on a single 4.54 ms figure that no row of the concurrency sweep reproduces; the “9x less memory” claim uses the widest of three memory pairs, and the homepage labels that peak RSS figure “memory at rest”.
- The “~4.5x more requests per dollar” arithmetic is correct, but it is a cost model priced on an assumed 4 vCPU / 16 GB instance, not a measurement.
- The Rust beta genuinely uses less CPU and less memory in every file, and leads in an exploratory concurrency-256 run.
- The configurations differed: LiteLLM reports logging off for every gateway, while the published Bifrost v1.6.4 config appears to leave default logging on, a finding inferred from v2.4.0 code and not yet confirmed on v1.6.4.
The three headline claims at a glance
Two of the three headline multipliers are not supported as stated by LiteLLM’s published data, and the third is correct arithmetic on modeled inputs. The 7x overhead figure is not reproducible from the sweep, the 9x memory figure points the right way but uses the widest pair under the wrong label, and the 4.5x cost figure is an estimate. All figures below are as of November 1, 2026.
LiteLLM published the claims in two places: a benchmark section on its homepage and a longer benchmark blog post. The blog says the Rust gateway has “roughly 7x lower overhead and 9x less memory than the next-closest gateway (Bifrost)”. The homepage shows tiles of 0.66 ms p99 added latency, “~22 MB memory at rest” and “~4.5× more requests per dollar”. The raw numbers behind both sit in the results/ folder of LiteLLM’s ai-gateway-bench repository.
Each claim below is compared with those files as of November 1, 2026. The table summarizes where each headline lands.
| Claim | Where it appears | What LiteLLM’s files show | Verdict |
|---|---|---|---|
| ~7x lower overhead (4.54 ms vs Rust’s 0.66 ms) | Blog; homepage tiles | 4.544 vs 0.66 ms in overhead_comparison.csv, which states no concurrency. The sweep shows +0.75, +0.63, +0.89, +28.68 ms against Rust’s +0.89, +0.61, +0.33, +40.28 ms | Not reproducible from the sweep |
| 9x less memory (199.1 MB vs 21.8 MB) | Blog (“peak memory”); homepage (“memory at rest”) | Three pairs in the files: 199.1 vs 21.8 MB, 144 vs 26.1 MB, 282 to 298 vs 35 to 36 MB. The column is peak_rss_mb | Rust is smaller; homepage uses the widest pair and mislabels peak RSS as memory at rest |
| ~4.5x more requests per dollar | Homepage | 283,833 vs 63,246 requests per dollar-hour in rps_per_dollar.csv | Accurate arithmetic, modeled inputs |
| Throughput “2,800+ req/s” | Homepage | The comparison cell is a dash; files show 2,744 vs 2,814 req/s, and 2,719 vs 2,722 in the sweep | Blank cell hides a gap of 2.5% or less |
This article covers all three claims at summary level, along with the setup, the configuration gap, where Rust leads and what a follow-up test will check. The full claim-by-claim record, including the smaller footnotes, is in The Frontier Wire’s fact-check of LiteLLM’s benchmark claims.
How LiteLLM’s benchmark was run
LiteLLM’s benchmark sends the same load to a deterministic mock upstream, once directly and once through each gateway, and reports the difference as added latency. It ran on a single host, each cell appears to be one run, and no machine type, core count or worker count is published for any gateway.
The blog defines overhead as gateway latency minus direct-to-mock latency and charts it as p99 added latency. Because the upstream is a mock that answers the same way every time, the difference is meant to isolate the gateway’s own cost. Figure 1 shows the shape of the measurement.
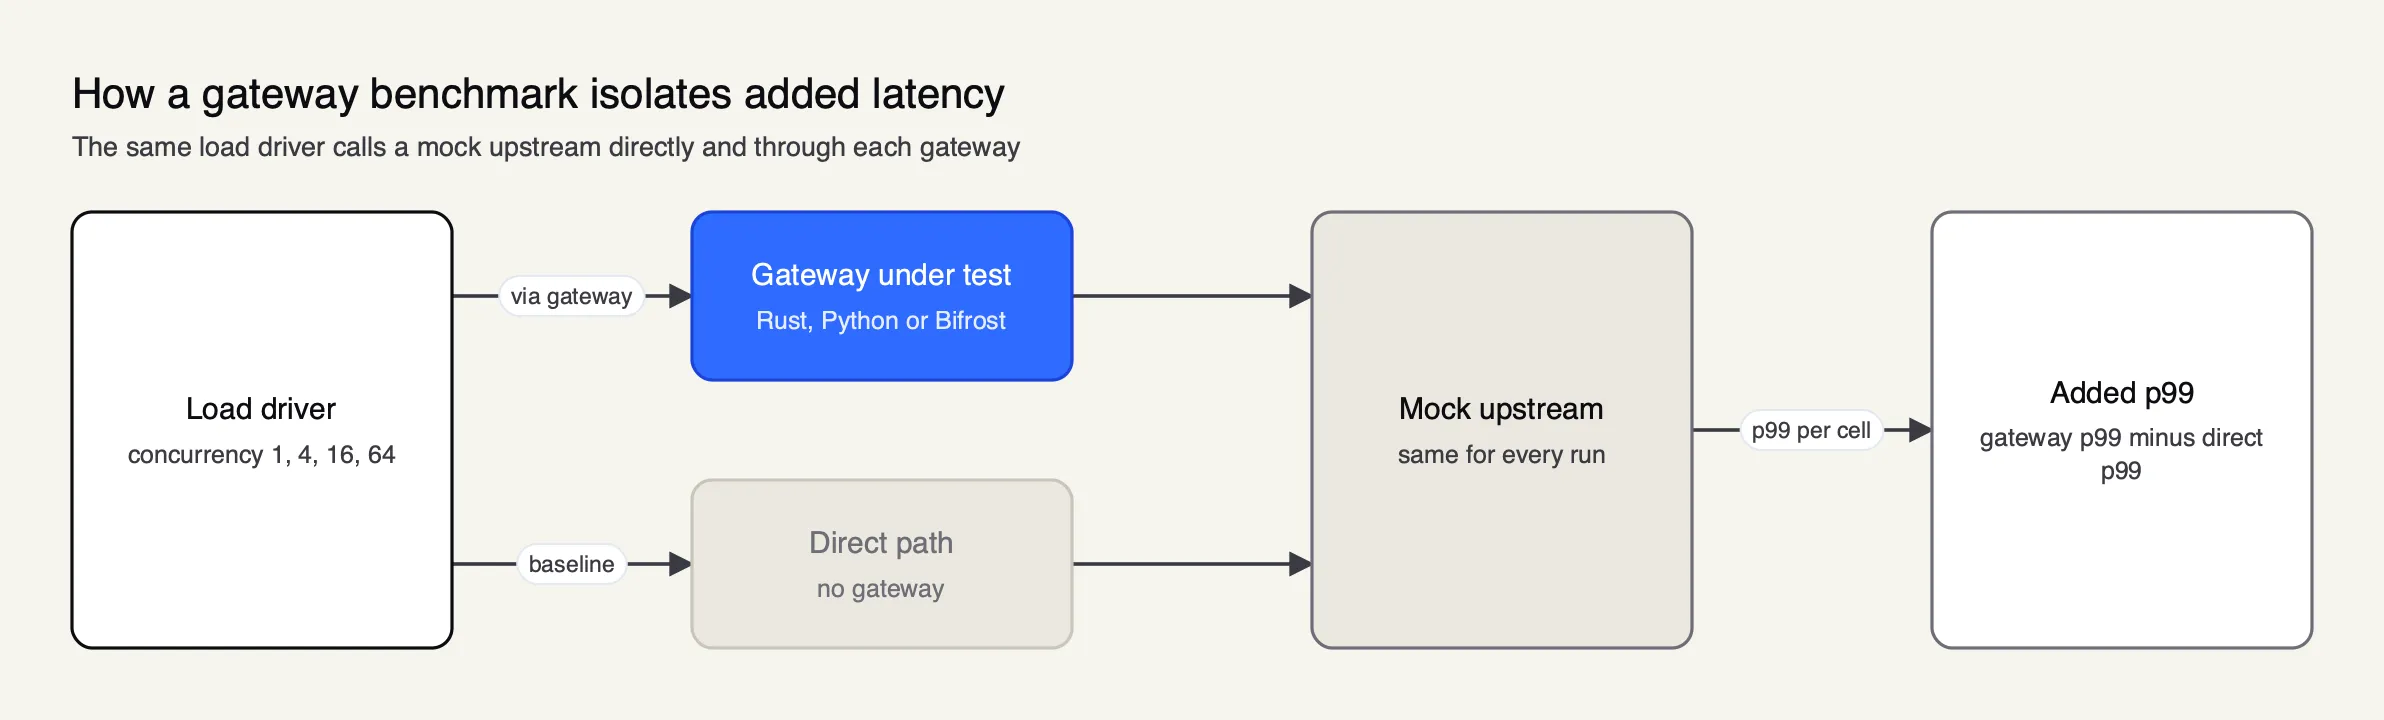 Figure 1: Added latency is a difference between two runs, so it is only as stable as the single runs behind each cell.
The blog lists the versions as the LiteLLM Rust beta, LiteLLM Python v1 (litellm[proxy]), Bifrost v1.6.4 (an open-source AI gateway) and the current open-source build of a fourth gateway, run with the “same mock and load driver on one host”. It names no Python v1 version and no hardware. It describes the Rust build as “an early beta, streaming and the full feature surface are still landing”. Bifrost’s changelogs list v1.6.5 to v1.6.11 and then v2.0.0 to v2.4.0 after the tested build, and the version is not shown on the homepage. The Frontier Wire’s piece on version parity in software benchmarking looks at what that gap means for the comparison. Bifrost was called on its native /anthropic/v1/messages route; the repo’s gateway README says v1.6.4 does not mount that integration at /v1/messages.
The blog is candid about the limits. It calls the results “single-host, per-scenario runs (for example n=5000 on the overhead panel) without repeated-trial error bars”, says to “treat them as order-of-magnitude differences”, and calls it “a vendor-run benchmark”. The homepage tiles do not repeat those caveats. The homepage says “Identical hardware”, but neither page names the hardware, and its “See the benchmark” link points to an in-page anchor rather than to the raw data or a methodology document.
Single runs matter more than they sound. The Frontier Wire’s analysis of benchmark sizes and statistical noise makes the general case: without repeated trials and error bars, small gaps between two systems cannot be told apart from noise. In LiteLLM’s own files, the ranking at concurrency 64 flips between documents. Total p99 for the v1.6.4 build is 52.7 ms in the sweep and 32.2 ms in rps_per_dollar.csv; for Rust it is 64.3 ms and 26.9 ms.
The 7x overhead figure
The 7x overhead claim compares a figure of 4.54 ms with Rust’s 0.66 ms, and no row of LiteLLM’s concurrency sweep comes close to 4.54 ms. In the sweep, the two gateways trade places: the v1.6.4 build adds less p99 latency at concurrency 1 and 64, Rust adds less at 16, and the gap at 4 is 0.02 ms.
The 4.54 ms value comes from overhead_comparison.csv, which lists 4.544 ms and 0.66 ms for the two gateways and states no concurrency. The sweep in latency_vs_concurrency.csv tells a different story. All error counts in it are 0.
| Concurrency | Direct p99 (ms) | LiteLLM Rust added p99 | Bifrost added p99 | LiteLLM Python added p99 |
|---|---|---|---|---|
| 1 | 21.98 | +0.89 ms | +0.75 ms | +9.79 ms |
| 4 | 22.42 | +0.61 ms | +0.63 ms | +26.95 ms |
| 16 | 22.67 | +0.33 ms | +0.89 ms | +251.34 ms |
| 64 | 24.02 | +40.28 ms | +28.68 ms | +546.04 ms |
At concurrency 1 to 16, the v1.6.4 build adds under 4% of the roughly 22 ms direct p99. Rust’s clearest latency lead is at concurrency 16, where it adds 0.56 ms less (+0.33 vs +0.89 ms); that is 2.7x the added latency but about 2.4% of total p99. At concurrency 64, it adds +28.68 ms against Rust’s +40.28 ms, about 29% less.
The homepage also carries a separate line: “3.5× lower overhead than the next AI gateway”. That comparison is against a different gateway in LiteLLM’s chart, at 2.29 ms, not against Bifrost. The page’s 3.5x and the blog’s “roughly 7x” are two different comparisons, and only the second involves the v1.6.4 build. The Frontier Wire’s breakdown of the 7x overhead figure traces the 4.54 ms number row by row.
Throughput: a tie with a blank cell
At concurrency 64, LiteLLM’s sweep records 2,722.2 requests per second for the Rust beta and 2,719.1 for Bifrost, a gap of about 0.1%. Every throughput gap between the two in the sweep is under 1%, which, with one run per cell and no confidence intervals, is within noise.
| Concurrency | Direct (RPS) | LiteLLM Rust | Bifrost | LiteLLM Python |
|---|---|---|---|---|
| 1 | 46.2 | 45.2 | 44.8 | 34.4 |
| 4 | 184.5 | 181.2 | 180.2 | 92.7 |
| 16 | 735.6 | 721.8 | 722.7 | 158.4 |
| 64 | 2,855.7 | 2,722.2 | 2,719.1 | 179.8 |
At concurrency 64, the v1.6.4 build keeps 95.2% of direct throughput and Rust keeps 95.3%. The homepage’s throughput tile reads “2,800+ req/s” for Rust and leaves the comparison cell as a dash. The rps_per_dollar.csv file has 2,744 req/s for the v1.6.4 build against 2,814 for Rust, so the blank cell hides a gap of 2.5% or less.
The larger gap in the same table belongs to LiteLLM’s Python proxy. It adds 546 ms of p99 at concurrency 64, about 13.6x the Rust port, and reaches about 180 RPS, roughly 6% of direct. Read as a whole, the sweep shows LiteLLM Rust catching up to where Bifrost already was, not Rust beating Bifrost. Teams weighing a move off the Python proxy will find the operational side covered in The Frontier Wire’s comparison of LiteLLM alternatives, and the vendor’s own steps in a guide to migrating from LiteLLM.
The 9x memory figure
The Rust beta uses less memory than the v1.6.4 build in every file LiteLLM published, so the direction of the memory claim holds. The 9x figure, however, comes from the widest of three memory pairs, and the homepage labels it “memory at rest” when the data is peak resident set size (RSS).
The headline pair is 199.1 MB against 21.8 MB for Rust, from mem_bifrost_messages.csv and mem_litellm_rust_release.csv. Two other pairs sit in the same folder: 144 vs 26.1 MB (mem_bifrost.csv, mem_litellm_rust.csv) and 282 to 298 vs 35 to 36 MB (cpu_*.csv). Those give ratios of 9.1x, 5.4x and 8.3x. The pairs may come from different scenarios or builds, so the problem is the label, not the headline number.
The label matters because peak RSS and resting memory answer different questions, as Figure 2 shows. The homepage chart uses “memory at rest”, “peak RSS” and “idle” for the same figure, and its note describes “resident memory with the gateway idle”. The column is peak_rss_mb. LiteLLM’s blog, by contrast, correctly says “peak memory”.
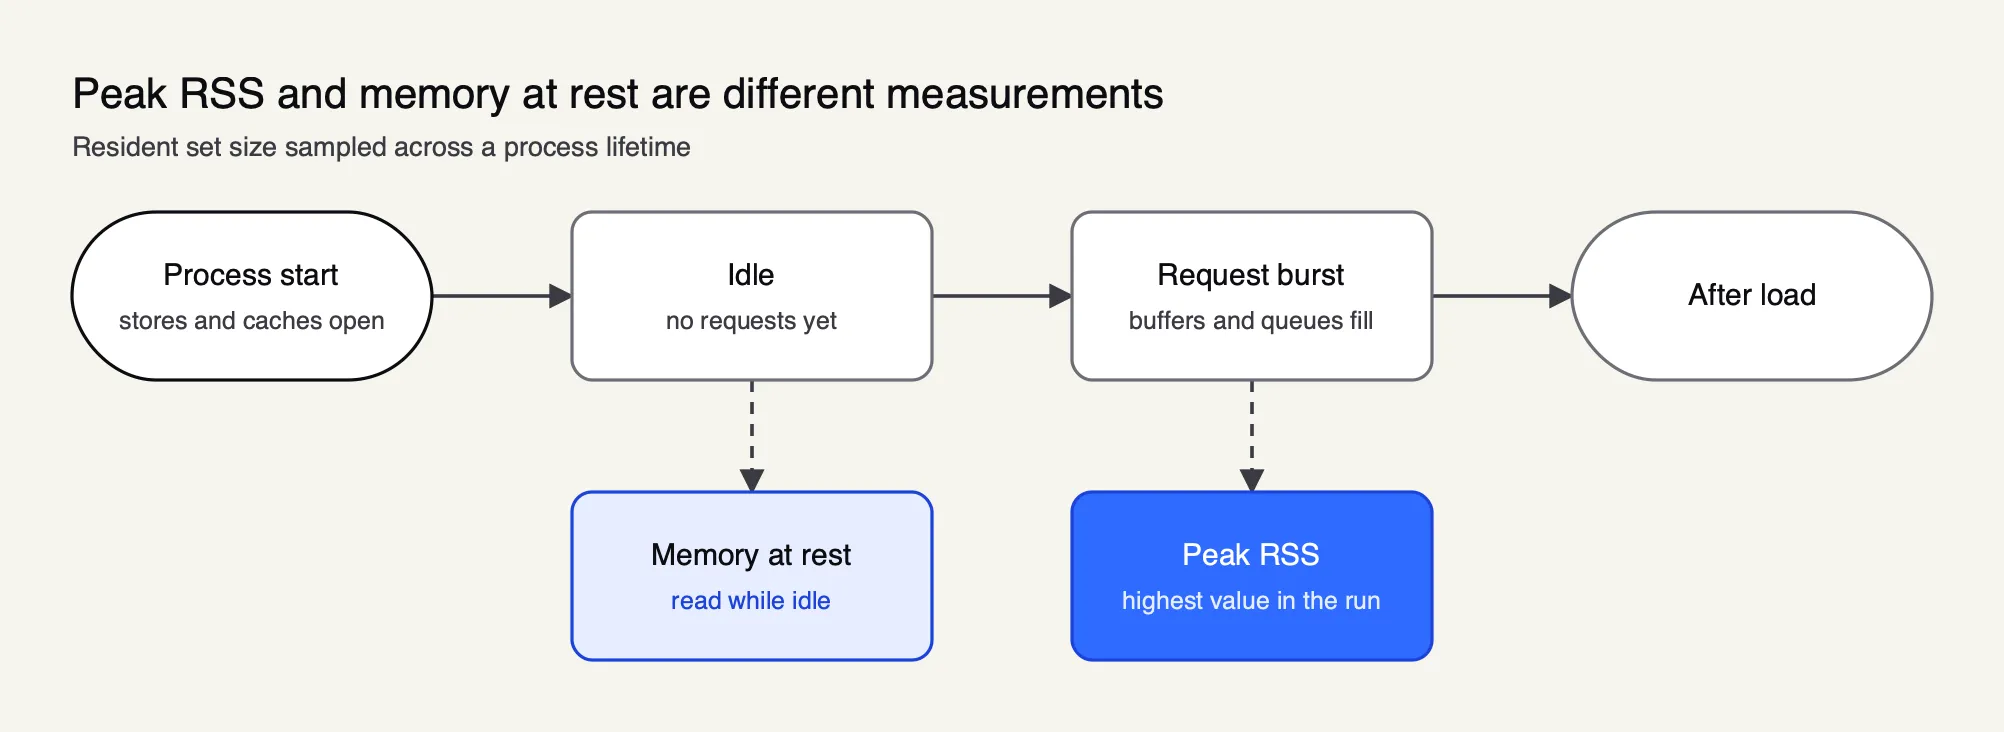 Figure 2: A column named peak_rss_mb records the highest point of the run, not the idle footprint a label like memory at rest implies.
Where the larger footprint comes from is less settled. In cpu_bifrost.csv, RSS is already about 282 MB before the first request, and load adds only about 16 MB. That points primarily to a baseline footprint rather than growth in the log buffer, though RSS alone cannot identify which components account for it. One candidate is SQLite: v1.6.4 opens a disk-backed logs.db at startup with a suggested cache limit of 10,000 pages per connection, approximately 39.1 MiB at a 4 KiB page size. That cache grows on demand under SQLite’s cache semantics, and the files do not quantify its contribution or isolate logging’s share of the gap.
Bifrost 2.x is reported to have since reduced memory use by changing what data it retains and how it stores it. No figure has been published yet; that is for Part 2.
The 4.5x requests-per-dollar model
The “~4.5x more requests per dollar” figure is correct arithmetic on a cost model, not a measured saving. It divides 283,833 by 63,246 requests per dollar-hour, numbers derived from measured CPU, peak RSS and throughput priced on an assumed 4 vCPU / 16 GB instance that is not the benchmark machine.
The homepage does not show those inputs. LiteLLM’s blog describes the method as “estimated USD per one million requests from measured CPU, peak RSS, and sustained throughput on a 4 vCPU / 16 GB instance”, and says the estimate “excludes token cost, which dominates any real bill”. Three ratios appear across LiteLLM’s materials:
- Per dollar-hour: 283,833 vs 63,246 requests, the homepage’s ~4.5x.
- Per million requests: $0.000175 for Rust vs $0.001008 for the v1.6.4 build, which the blog calls “roughly 6x”; computed from those two numbers it is about 5.8x, and it is a different metric from the page’s 4.5x.
- Per hour: a modeled footprint of $0.0434 against $0.0099 for Rust, a 4.4x ratio.
Because the model uses measured CPU and peak RSS as inputs, any extra work a gateway did during the run flows into its modeled cost. The v1.6.4 build’s logging cost is inside those inputs. That leads to the configuration question.
The logging configuration mismatch
LiteLLM’s blog says every gateway ran “with no logging callbacks, spend tracking, or persistence enabled”, but the published v1.6.4 config appears to leave default logging on. The finding is inferred from v2.4.0 code and not yet confirmed on v1.6.4, the version tested.
The v1.6.4 config in LiteLLM’s repo points at the benchmark’s test upstream, sets config_store: enabled: false and lists no plugins. It never sets logs_store or enable_logging. Read against the code, this is what that leaves running:
enable_loggingdefaults to true when unset.- A missing
logs_storecreates a default SQLite log store. - The logging plugin is built in, so “no plugins” in the config does not turn it off; it loads when
enable_loggingis unset or true and a log store exists. - Other built-in plugins stay on: telemetry unless disabled, governance in the open-source build, routing with governance, and compat, which is always registered.
config_store.enabled: falseonly leaves the config store empty; it does not turn off the log store or the plugins.disable_content_loggingdefaults to false, so request and response bodies are logged too.
The gateway’s public observability documentation describes enable_logging as the master toggle for request tracing and disable_content_logging as the switch that drops request and response content while keeping usage metadata. Its gateway setup guide explains that config_store.enabled: false makes config.json the only configuration source, which is a separate setting from logging. Figure 3 shows the two workloads.
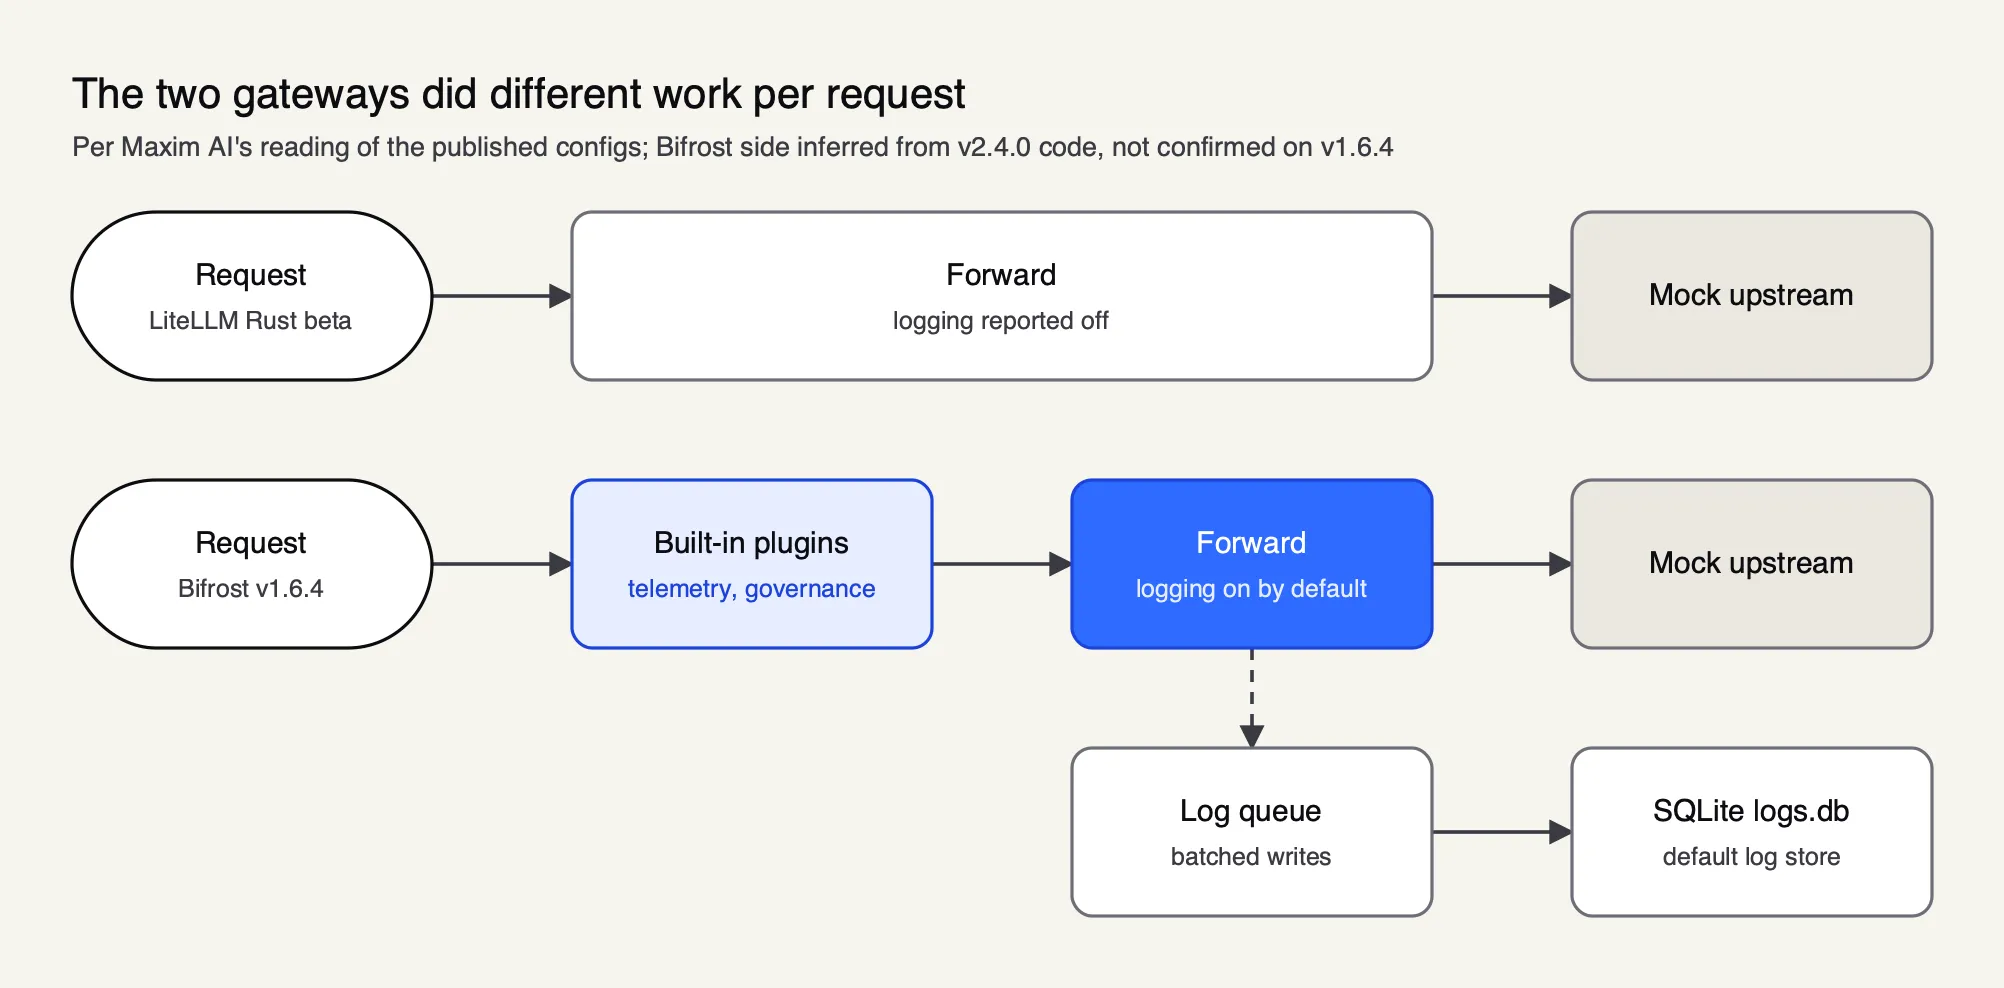 Figure 3: A forwarding-only run and a run that also writes logs measure different workloads, which is why a like-for-like test needs logging on and off.
Two limits apply to this finding. The LiteLLM Rust config was not checked. A controlled rerun is also needed to measure what logging contributed, because disabling logging alone does not remove the other plugins’ hooks. The Frontier Wire’s explainer on logging performance in gateway benchmarks walks through that configuration gap in more detail. For anyone rerunning the test, client_config.enable_logging: false removes the built-in logging plugin’s queue and hooks at startup, while client_config.disable_content_logging: true reduces logged payloads.
Where the Rust gateway genuinely leads
LiteLLM’s Rust beta leads Bifrost v1.6.4 on CPU, on memory in every file, at concurrency 16 in the latency sweep, and in an exploratory concurrency-256 run. Those leads are real in the files. They describe the tested configurations, though, and do not establish an equivalent-feature performance advantage.
| Measure | LiteLLM Rust | Bifrost v1.6.4 | Caveat |
|---|---|---|---|
| CPU, mean | 0.66% | 2.59% | Whole-process, under the configurations described above |
| CPU, peak | 15.9% | 79.5% | Bifrost peak falls inside a roughly two-second request burst |
| Memory | About 36 MB at most | About 144 MB at least | Rust smaller in every file |
| Added p99, concurrency 16 | +0.33 ms | +0.89 ms | One run per cell |
| p50, concurrency 256 | 55.5 ms | 89.3 ms | Exploratory: one run, no RPS field |
| p99, concurrency 256 | 2,667.8 ms | 5,421.3 ms | Exploratory: one run, no RPS field |
On CPU, the Rust beta averages about 3.9x less CPU by mean and about 5x less by peak, from cpu_rust.csv and cpu_bifrost.csv. The files do not separate request handling from background work. None of the Rust CPU, throughput, cost or overhead files checked contains the homepage’s “~21% CPU” figure, and the CPU samples appear, though this is unconfirmed, to come from a short burst, probably the concurrency-16 cost runs.
The concurrency-256 run was dropped from the sweep because the direct baseline’s p99 exceeded twice the single-client floor, according to the repo README, but a JSON file for each gateway is still in results/. Rust leads by about 1.6x at p50 and 2.0x at p99, and the v1.6.4 build leads LiteLLM Python by about 17x at p50 and 2x at p99. With the baseline already outside the benchmark’s threshold, it is an exploratory result rather than a reliable capacity comparison.
The homepage’s “single client” footnote does not match the files either. The sweep runs concurrency 1 to 64 and the throughput point uses a ceiling concurrency of 64. The footnote is misleading.
What the Rust beta covers today
The gateway LiteLLM benchmarked is a narrower Rust beta, not the full LiteLLM product rewritten in Rust. LiteLLM’s own documentation says most production routes, including Chat Completions and Messages, still run on Python in main:latest.
As of November 1, 2026, GitHub’s language breakdown for BerriAI/litellm showed 84.88% Python, 3.11% Rust and 12.01% other languages by source-code bytes. That count includes tests and supporting code and does not mean 3.11% of features or traffic run on Rust. LiteLLM’s migration tracker reports 24% of Major APIs built as of v1.107.0-rc.2 (35.4 of 146 weighted points), with router migration, database access, budgets and rate limits, and database-backed configuration at 0%.
The Rust gateway documentation carries a warning: in main:latest, the Python proxy uses Rust for /ocr across providers and for /audio/transcriptions on Bedrock. Other routes, including Messages and Chat Completions, run on Python, and the per-model rust: true flag currently has no effect. The existing Python proxy still owns authentication, routing, logging, callbacks and spend tracking.
For teams running LiteLLM today, that changes how to read the sweep. In main:latest, Chat Completions and Messages traffic is served by the Python proxy, the gateway that adds +546.04 ms of p99 at concurrency 64 in the same file, and LiteLLM’s benchmark blog says its setup isolates forwarding overhead and “is not a full-feature comparison”. Such results cannot establish the performance of the complete production feature set. Readers comparing gateways on features rather than this benchmark can start with The Frontier Wire’s survey of the best AI gateways and its guide to open-source AI gateways.
What Part 2 will test
A planned Part 2 follow-up will rerun the comparison like-for-like, with the disclosures LiteLLM’s benchmark omits. It commits to four changes, each aimed at a gap identified above: the logging mismatch, the old build and single runs, the missing hardware details, and the unexplained memory footprint.
- Logging off and on. Both gateways run with logging off, and again with logging on.
- A current build. Repeated trials with error bars, instead of single runs on v1.6.4.
- Full disclosure. Hardware, worker counts, mock latency and concurrency published for every run.
- Heap profiles. A profile to measure how much of the memory gap is the log buffer.
Until then, no current-build performance figure is available, and the memory improvement in 2.x is described without a number. The vendor’s own comparison pages, such as a feature-by-feature LiteLLM and Bifrost comparison and a look at high-throughput workloads, are vendor material and are best read alongside the raw files.
What the benchmark supports
LiteLLM’s published data supports a narrower claim than its homepage makes: the Rust beta matches Bifrost v1.6.4 on latency and throughput at most tested concurrency levels and uses less CPU and memory, under configurations that did different work. It does not support a 7x overhead gap, and the memory and cost figures need their labels and assumptions attached.
For an engineer reading any gateway benchmark, the LiteLLM Rust benchmark is a useful worked example of what to check before trusting a multiplier:
- Does the headline number appear in the sweep? A single figure from a file with no stated concurrency is weaker than a full row-by-row sweep.
- Is the memory figure peak or resting? The two measure different things, and the label should match the column.
- Is the cost figure measured or modeled? A modeled cost on an assumed instance is an estimate of footprint, not a bill.
- Did every system do the same work? A logging-on run and a logging-off run are not a like-for-like test.
- Are there repeated trials and error bars? Without them, sub-millisecond and sub-1% gaps are noise.
The repository’s openness is what made this check possible. Every plotted value is a committed file, which is the reproducibility guardrail LiteLLM’s blog itself sets. Bifrost’s source is likewise public in its GitHub repository, and teams evaluating a switch can read the vendor’s LiteLLM alternative overview and its migration walkthrough as vendor documentation. The verdict on the LiteLLM Rust benchmark, as of November 1, 2026, is that its direction on resource use holds and its headline multipliers do not hold as stated. A like-for-like rerun with published hardware and error bars is the test that would settle the rest.
Source: Debunking LiteLLM Rust Benchmarking: Part 1, by Akshay Deo of Maxim AI, which builds the Bifrost gateway.
Sources
- Debunking LiteLLM Rust Benchmarking: Part 1 (Akshay Deo, Maxim AI, November 1, 2026)
- LiteLLM homepage benchmark section (litellm.ai)
- LiteLLM blog: Rust AI gateway benchmarks (methodology)
- LiteLLM docs: [Beta] Rust AI Gateway
- LiteLLM Rust migration tracker
- BerriAI/ai-gateway-bench: results directory
- ai-gateway-bench: latency_vs_concurrency.csv
- ai-gateway-bench: overhead_comparison.csv
- ai-gateway-bench: rps_per_dollar.csv
- ai-gateway-bench: cpu_bifrost.csv
- ai-gateway-bench: cpu_rust.csv
- ai-gateway-bench: Bifrost gateway config and README
- GitHub language breakdown for BerriAI/litellm
- Bifrost docs: built-in observability and logging settings
- Bifrost docs: setting up the gateway (config store modes)
- SQLite documentation: PRAGMA cache_size
Questions readers ask
Is LiteLLM's Rust gateway really 7x faster than Bifrost?
Not on LiteLLM's own concurrency sweep. The 7x comes from a single 4.54 ms Bifrost overhead figure in overhead_comparison.csv, a file that states no concurrency. In the sweep, the two gateways add +0.75 vs +0.89 ms of p99 at concurrency 1, +0.63 vs +0.61 ms at 4, +0.89 vs +0.33 ms at 16 and +28.68 vs +40.28 ms at 64 (Bifrost first). No row is near 4.54 ms.
Does LiteLLM Rust use less memory than Bifrost?
Yes. LiteLLM's Rust beta records lower memory in every file of the benchmark repository, and its highest figure (about 36 MB) is below Bifrost's lowest (about 144 MB). What is wrong is the label: the homepage calls the 199.1 MB vs 21.8 MB pair memory at rest, but the data is peak RSS. That pair is also the widest of three in the files.
Were LiteLLM Rust and Bifrost benchmarked with the same settings?
The published configs suggest not. LiteLLM's blog says every gateway ran with no logging callbacks, spend tracking or persistence. The Bifrost config never set enable_logging or a log store, and in Bifrost's code those defaults turn logging and a SQLite log store on. That finding is inferred from v2.4.0 code and not yet confirmed on v1.6.4, the version tested.
Is the 4.5x requests-per-dollar figure measured?
The arithmetic is correct (283,833 vs 63,246 requests per dollar-hour gives 4.5x), but the figure is modeled. It is derived from measured CPU, peak RSS and throughput priced on an assumed 4 vCPU / 16 GB instance, which is not the benchmark machine. LiteLLM's blog gives a different ratio, roughly 6x per million requests, which works out to about 5.8x.
What will the Part 2 follow-up test?
Part 2 will run both gateways with logging off and again with logging on, use a current Bifrost build with repeated trials and error bars, publish hardware, worker counts, mock latency and concurrency for every run, and take a heap profile to measure how much of the memory gap is the log buffer.